
Business Understanding for Sofia AirPollution Prediction
Background and Motivation
In Sofia, Bulgaria, air pollution norms have exceeded exponentially in period from October 2017 to March 2018. Things got so out of control that even the European Court of Justice ruled against Bulgaria in a case brought by the European Commission against the country over its failure to implement measures to reduce air pollution.
The two main reasons for the air pollution are believed to be:
- solid fuel heating and,
- motor vehicle traffic
Sofia has 5 metropolitan weather stations that captures weather data on an hourly intervals. In addition, a new initiative was launched to help gather lot more data from more locations across Bulgaria.
The AirBG.info project was launched on April 5, 2017, founded by Nikolay Luchev and Stefan Dimitrov and is part of the global project Luftdaten.info, which started in Stuttgart in 2015. This is an independent civil project aimed at bringing more light to these :
- excessive contamination with PM;
- gasification of settlements;
- missing or insufficient measurement of air quality by the authorities;
- insufficient measures taken by the legislative, municipal and executive authorities.
The focus of this study and project is specifically aimed at study of air pollution from particulate matter. Particulate matter (PM), is the term used for a mixture of solid particles and liquid droplets found in the air. Fine particles with diameter between 2.5µm and 10µm are called PM10, while particles with diameter less than 2.5 are referred to as PM2.5.
Prediction of PM10 in the atmosphere over Sofia, is an important issue in control and reduction of pollutants in the air. European Commission has described a threshold of 50 micrograms/cubic meter as the critical threshold above which air above Sofia is considered highly polluted.
Business Objective
The goal of this project is to forecast concentration for the PM10 pollutants in next 24 hour period given the data from the Citizen Data AirGB.info project and the official weather data from the official sites with a high degree of accuracy (90%+).
Business Success Criteria:
The desired result is a map that can cover any location of the city and be able to forecast the PM10 concentration in the next 24 hours with a high degree of accuracy(90%+). An example of map from AirBG.info is shown below.
Assumptions:
While not specifically called out, the following assumptions are prudent to make:
- Main sources of pollution are assumed to be:
- solid fuel heating and,
- motor vehicle traffic
- That measuring PM10 is sufficient to capture the pollution affects of both solid fuel heating and motor vehicle traffic.
- There may be gaps in the Official Meteorological data making it insufficient to inform the bigger picture of air pollution across Bulgaria all by itself
- The accuracy of the metrics received from the Citizen Weather Stations does not conform to the strict standards of the equipment used in official stations
- More data is better than higher quality data
- The cost to quality trade off is acceptable to inform the larger picture
Constraints:
This project is being run under constraints of a data science challenge which is time limited and requires other commitments governed by its learning goals.
This project is being run across multiple teams with one or more people per team who may interpret the problem differently and may make different assumptions that aren’t directly validated with the business users.
The equipment available to work on the larger data sets may not be sufficient to process and run algorithms in a timely fashion. While sensor data is available at large volumes, the ability to read, store, process and use that data maybe limited by the constraints imposed by the challenge.
Defining The Data Mining Problem
The project provides two distinct data sets that could represent multiple versions of the truth.
- Official Meteorological Data
The official data is used for law suits, policy creation etc. With the far reaching implications, the official data is gathered only from 5 stations, named after neighborhoods and provides meteorological measurements such as temperature; humidity; pressure etc. This data has longer history, but it’s not spread out across the country. AirBG.info brings to question the quality of this data by suggesting this may have missing data and insufficient measures on the part of the authorities to provide a full representation of Sofia’s air pollution problem.
- Citizen Meteorological Data
The Citizen data is gathered from the AirBG.info initiative that is not a government funded and is run by volunteers and citizens of Bulgaria. Each citizen that wishes to participate builds a weather monitoring kit from standardized parts. These citizen weather stations upload data every 5 minutes via an onboard WIFI connectivity and is voluminous in nature. This data has shorter history but is spread across a lot more than 5 stations.
In addition it provides data topography data includes Sofia urban area + some areas nominally external to the city (toward the mountains, note large elevation numbers). No particular effort has been made to include entirety of Sofia Capital’s area as per administrative boundaries. This topographical data includes lat/long and elevations for several areas in and around Sofia.
Last but not least, the project allows access to API’s that would allow it to gather, inspect and mine data from Citizen Weather station sensors.
Data Understanding
This section focuses on understanding the data, uncover data quality issues and discover first insights and detect interesting subsets of data.
Data Sources
Data was originally distributed from the following data source (which is used as the single version of truth for the raw data set)
https://storage.cloud.google.com/global-datathon-2018/sofia-air/air-sofia.zip
Additional data available for consideration:
- All sensor values in the last 5 minutes from the registered stations as JSON files, which are updated every minute -> http://api.luftdaten.info/static/v1/data.json
- Values from the last 5 minutes of a particular sensor -> http://api.luftdaten.info/v1/sensor/sensorid/
The zip files consists of several different sources of data gathered in different ways.
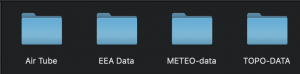
Figure: The figure above shows the directory structure of the root folder after unzipping the source data
The Air Tube Data
This data is sourced from a citizen initiative. Sofia citizen use non-portable equipments to report the following information in the columns:
- time
- geohash
- P1 – PM10 concentration
- P2 – PM 2.5 concentration
- humidity
- pressure
- temperature
The citizen data is available in 2 files one for each year – 2017 and 2018. Presumably this initiative is new and data from the initiative would be reflective of the adoption of the initiative among the citizens of Sofia and its ramp, dispersion etc.
File Name: ./Air Tube/data_bg_2018.csv ==> Citizen Data gathered in 2018
File Name: ./Air Tube/data_bg_2017.csv. ==> Citizen data gathered in 2017
File Name: ./Air Tube/sample_data_bg_2018.csv ==> sample data file
Across each of these files there are 1254 unique geohashe’s, each representing a location for the citizen data. Since these unit’s are not portable, we can assume then that this represents the sample size of the number of Sofia citizens participating in the initiative. While this is significantly better than the 5 meteorological measurements sites officially maintained, it is to be seen if these citizen generated data points are reliable .
Notable Point on Reliability.
How much variance do they have form the norm? If high variance, does it show bad instrument design, placement decision of the instruments or perhaps it is a valid measurement that shows actual and correct measurement for the PM10 pollutant. What if the citizen measurement device was placed on a fire place near a high humidity environment where wood is being burnt? Just a simple choice of placement for such devices could deliver alarming data into the data set that perhaps is not completely correct.
Data Characteristics
After reindexing the data on time, the following shows the size and the number of records in the data set in each of the file:
File Name: ./Air Tube/data_bg_2018.csv
| Pre Geo Hash To Lat/Long Conversion | Post Geohas to Lat/Long Conversion |
|
Pre Data wrangle raw data analysis Data Shape: (2958654, 7) Show column counts with null/nans time 0 geohash 4 P1 0 P2 0 temperature 0 humidity 0 pressure 0 dtype: int64
Total geo hashses 2958654 Unique geo hashses 1254 Total time stamps 2958654 Unique time stamps 5461 data_wrangle_citizen_data: shape: (2958654, 7)
|
Post Wrangling Data Shape: (2958654, 9) Show column counts with null/nans time 0 geohash 4 P1 0 P2 0 temperature 0 humidity 0 pressure 0 Latitude 0 Longitude 0 dtype: int64 Total geo hashses 2958654 (consistent with raw) Unique geo hashses 1254 (consistent with raw) Total time stamps 2958654 (consistent with raw) Unique time stamps 5461 (consistent with raw) |
File Name: ./Air Tube/data_bg_2017.csv
File Name: ./Air Tube/data_bg_2017.csv
| Pre Geo Hash To Lat/Long Conversion | Post Geohas to Lat/Long Conversion |
|
Pre Data wrangle Data Shape: (651492, 7) Show column counts with null/nans time 0 geohash 0 P1 0 P2 0 temperature 0 humidity 0 pressure 0 dtype: int64
Total geo hashses 651492 Unique geo hashses 383 Total time stamps 651492 Unique time stamps 2774 data_wrangle_citizen_data: shape: (651492, 7) |
Post Wrangling Data Shape: (651492, 9) Show column counts with null/nans time 0 geohash 0 P1 0 P2 0 temperature 0 humidity 0 pressure 0 Latitude 0 Longitude 0 dtype: int64 Total geo hashses 651492 Unique geo hashses 383 Total time stamps 651492 Unique time stamps 2774 |
Insights: Growth of the Citizen Program & Reliability
227% growth in Citizen Stations:
From the data, it seem really positive that the citizen program has grown from 383 unique points reported in 2017 to 1254 stations in 2018 a 227% growth. That is phenomenal adoption by citizens of Sofia. However, it’s yet not clear if the data from the program is reliable.
354% growth in data signals
Total data signals recorded across all geohashcodes and across all time stamps grew from 651,492 to 2,958,654 an explosive 354% growth. Some of variance in the number of data signals may correspond to when the program was started.
Early adoption starting in Sept 2017
The first data point recorded in 2017 is : 2017-09-06T20:00:00 Z
The start day of the first recorded data signal is September 6th. We can infer that the program was started late in the year and it was in the infancy with some early adoption of 383 remote citizen stations. Based personal experience, a program with such magnitude may have challenges around onboarding, training, technical glitches before it can be in steady state.
49% reduction in reported time stamps for data signal
Unique time stamps reported changed from 5441 to 2774
While hard to say without looking more at the data, this reduction in data signals may look bad because we had more months during which the program was running in 2018 than in 2017.
A longer project perhaps would analyze the “reliability” of data signals from the originating geohash by examining features like consistency of reporting, data gaps, variance from norm to infer a set of geohashcodes that maintain a “high quality” of data gathering and perhaps be rewarded by the government. While geohash codes with significant data gaps or intermittent and consistent patterns of data signals may be put in a tier 2 bucket on reliability. Perhaps the every 5 minute data is more appropriate for this type of analysis.
Data Quality
In this section, I examine the quality of the data provided by exploring for bad data, gaps in data and informing next steps.
On using panda’s to explore this data closer, there were a few gaps.
Unparseable/bad geohash
File : AirTube\data_bg_2017 – Decoding Geohash’s using Pygeohash library
index: 133972: Encoded GeoHash: sxevuw2d6z6 Decoded Tuple: (43.233, 27.972)
index: 133973: Encoded GeoHash: sx8ddncmwhr Decoded Tuple: (42.665, 23.293)
index: 133974: Encoded GeoHash: sx8df3rr0yp Decoded Tuple: (42.679, 23.312)
index: 133975: Encoded GeoHash: sx8dcsn8b8n Decoded Tuple: (42.693, 23.278)
The next index throws a KeyError with “-” as the key. Likely unavailable data or data error
Since Excel and Apple Numbers only loads 65K rows of data. Finding the exact data point required iteration.
Iterating in pandas found the key as below:
index: 133974: Encoded GeoHash: sx8df3rr0yp
index: 133975: Encoded GeoHash: sx8dcsn8b8n
index: 133976: Encoded GeoHash: m-2105171
index: 133977: Encoded GeoHash: sx8dsqct9h7
On inputting this Geohash in a converted, it was obvious this was not good data point.
File : AirTube\data_bg_2018 – Decoding Geohash’s using Pygeohash library throws error for index 977238
Using panda’s code below we see that this file has NaNs’s in Geohash column.
c_df = pd.read_csv(aFileName, header=0, encoding=’utf-8′)
print(c_df.isnull().sum())
time 0
geohash 4
P1 0
P2 0
temperature 0
humidity 0
pressure 0
dtype: int64
Using a time indexed data frame to find the rows of data that have missing data.
time geohash P1 P2 temperature humidity pressure
977238 2018-04-02T10:00:00Z NaN 0 0 14 39 0
977818 2018-04-02T11:00:00Z NaN 0 0 14 36 0
978376 2018-04-02T12:00:00Z NaN 0 0 15 34 0
978961 2018-04-02T13:00:00Z NaN 0 0 15 31 0
Quality Gap Decision :
Neither of these quality gaps seemed important. So I decided to drop these from the data set.
Data Wrangling Code For Citizen Data
This is the Jupyter notebook for my data wrangling code.
SofiaCitizenDataWrangling_NeeleshKamkolkar
Aggregation of Citizen Data
By inspection Air Tube / Citizen data is arriving every 1 Hour with gaps in data across each of the stations. Each of the geohashes are going to need to be translated to lat/long for consistent location mapping across metro and citizen data. For this I will choose to use the pygeohash library.
import pygeohash as pgh.
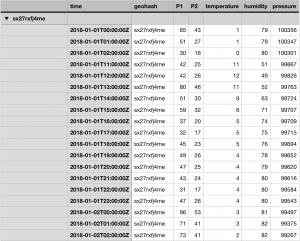
For example, in figure above, you can see citizen data gaps where data is not showing up hourly.
Top Down Data Exploration
This is looking at the data set as is without doing any wrangling. The following Tableau visualization shows some interesting insights that aren’t readily available for inspection.
Data Exploration – Tableau Viz
A monthly aggregated view shows Druzhba station having highest peaks during holiday/christmas times. Druzhba is at 548 meters altitude. This elevation is not very high and a relevant official weather station.
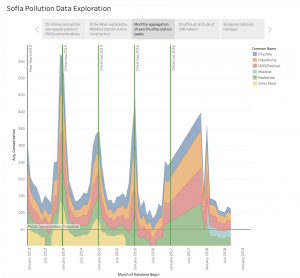
The readings are verified and validated by authority (per the verified and validated columns in data) – so these are legitimate values and not errors in instrumentation or outliers.
A daily view shows consistent pattern of average concentration of PM10 spiking in winter months around October, November, peaking in December and starting to recede through Jan and February.
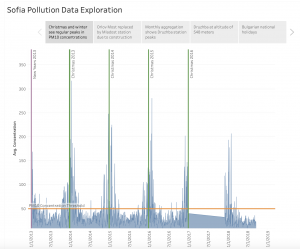
Noted missing data as part of a station being shut down due to construction and being moved.
Missing Data from Official Data sets
Also, deeper inspection of the data shows, regularly missing data hourly from 9-10 AM from Mladost station (BG0079A) for the critical 1st week of January. The readings in the hours following this missing data spike up significantly. What is the cause of these dropped data signals during these hours? Was there an instrument malfunction in the official weather stations. If the instruments are so costly relative to the citizen weather stations, then is it expected to be unreliable under some conditions.
Metro-Data (Pollution Concentration)
This data set shows varied aggregation levels through out the data set. For example, the “AveragingTime” column shows averaging by day on some rows and by hour on others without a corresponding daily roll up.
Varied Aggregation Levels:
Directory: “EEA Data”
Total File Count: 28
{File : AverageTime }
{‘./EEA Data/BG_5_9421_2013_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9421_2014_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9421_2015_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9421_2016_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9421_2017_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9421_2018_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9484_2013_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9484_2014_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9484_2015_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9572_2013_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9572_2014_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9572_2015_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9572_2016_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9572_2017_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9572_2018_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9616_2013_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9616_2014_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9616_2015_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9616_2016_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9616_2017_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9616_2018_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9642_2013_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9642_2014_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9642_2015_timeseries.csv’: ‘day’}
{‘./EEA Data/BG_5_9642_2016_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9642_2017_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_9642_2018_timeseries.csv’: ‘hour’}
{‘./EEA Data/BG_5_60881_2018_timeseries.csv’: ‘hour’}
Data Preparation Plan
| Why | What | How | Notes |
| Location is needed for final result to be shown as map and is a learning feature for NN | Bring lat/long/elev data into EEA Data metropolitan data from the metadata.xls file | Left merge EEA_Data with metadata.xls on AirQualityStationEoICode | Performance? Need to bring this in for each EEA Data files – 5 stations, 6 files per year with 6005 rows (one sample example file) each = 180,150 rows of data. Need to also bring in citizen data |
| Data size is large and requirement is to forecast at 24 hr. period. | Aggregated hourly meteorological data to daily (24 hours) | Pandas dataframe resample from hour to day | Need to do this for each file. |
| Need consistent aggregation across all data for accuracy | BG_5_60881_2018_timeseries.csv has ‘AveragingTime’ as hour | Resample with pandas | Not all files have same aggregation levels. |
| Level of detail for AverageTime should be day | 2016,2017,2018 have hourly averages, while earlier years have daily averages | Create and use DatetimeEnd as index and resample DataFrame to daily level of detail | Dataframe cannot have begin and end time stamps in index or have multi indexes. |
| Accurate inputs to model | Handle missing data in Mladost from 2013-2017 and in Orlov Most 2015-2018 | ||
| Accurate input to model | Handle missing data due to instrumentation failures | Data already cleansed for this. Missing values are recorded as -9999 | Handle these calculations. |
| Consistent location data across citizen and metro | Citizen (Air Tube) data is geohashed while metro data is in lat/long. | Convert Geohash to lat/long and add a new column. | |
Week 2
Based on some of the observations above, I accomplished two things this week.
- Explore the Official raw data (without first excluding any data points)
- Run a basic regression model on official data only before combining.
The data exploration is published here:
https://public.tableau.com/shared/RSFXGYTFM?:display_count=yes (Images copied below for ease, if resolution bad or cannot read, please view the link directly)
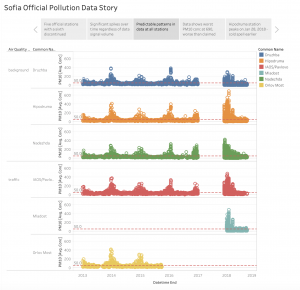
This view shows the average concentration of PM10 particles for each of the stations (color encoding) by whether the station was capturing air quality in the background or in traffic. The threshold PM10 concentration of 50ug/m3 is show as the red dotted line to visualize how often the PM10 concentration is above the European Union’s specified norm.
Each of the official stations shows a very repeatable specific pattern in all data through out the time data was captured.
The fact that there is less data does not seem to dispel that there is a pattern in the data.
While some have suggested that data from 2017 and earlier be dropped, it assumes that less data is less useful. On the contrary this view shows that even though there is less data, the patter and time frames of cycles is very repeatable. Perhaps dropping that data may still be needed for improving performance of training ML, however, for now, I plan to keep all the data for training.
Note that the top three stations are categorized as ‘background” in the data while the bottom three are categorized as “traffic” for the AirQualityType
The gap shown in the data is due to one of the weather stations shutting down due to construction and a new one opening in a different location.
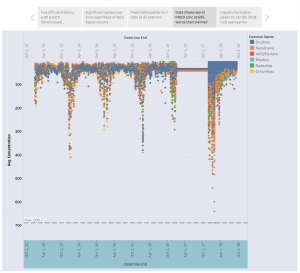
Continuing with the raw official data exploration, you see the inversion is having quite an impact on the PM10 concentration in the atmosphere – being bounced back into the populated areas, this top down bubble chart shows the average concentration for the PM10 particle over time increasing as you go down the screen (for visual affect of showing PM10 particles bouncing off the inversion ceiling. 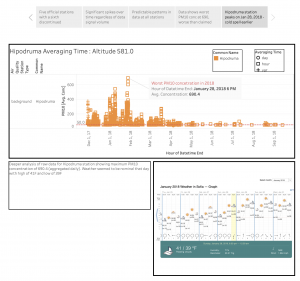
Each of the stations is color coded.
The one thing that stands out is that the Hipoduruma station shows a very high concentration of PM10 around 690.4 – which is far higher an instance level than suggested in the challenge to date.
This instance level data maybe useful in informing whether that specific station has a variability in some way form or shape that makes it an outlier. For now, I will proceed as though data from that station is correct and of high quality.
Drilling into the raw data for Hipodruma station which is at an altitude of 581 meters, the data seems to follow the same pattern for the year. However, weather prior to the maximum seems to have been nominal.
One thing that stood out is that for each peak in the data set, the prior 2-3 days had abnormally low temperatures. While the day of peak the temperatures maybe coming back higher, a hypothesis that could be formed is whether the prior fews days weather patterns can inform the trigger for a peak condition in PM10 concentrations.
Another observation about the official weather data is that data has different aggregation times marked by the column “AveragingTime” across various years and various stations the aggregation time changes from day, hour and “var”. The var was more prominent in 2013 than later years. Without knowing the sample boundary we may inadvertently divert from the pattern – but for now it would be safe to delete this data.
Believability In Data Growth
It seems that the official weather stations were averaging 507 records each year between 2013 through 2017. In 2018 ALONE, the average count of data signals across all official metro stations to **5,912.4.
This in just a little more than 10 times increase in data signals!
This jump is signals is excellent news for the environment measurements because the orginal assumption was that we needed more data. A positive inference that could be derived here is that the official stations are heading in the right direction.
However, unless there was a significant investment in people, process, technology and upgrades a 10 times jump in the data signals seems questionable in the least. At this time, I have no data to corroborate whether there is a corresponding investment that believably shows that this type of growth in data signals is possible.
Is 10 times growth in data signals sufficient?
Considering the lowest level of detail is an hour and many stations are reporting data on a daily basis(identified in the data by the ‘AveragingTime’ column), the maximum increase across 5 stations we could see, in theory:
24(hrs/day)x*365(days/year)x5 stations = 219,000 data signals if each of the 5 stations was reporting hourly in the considered 365 days with 100% reliability.
Ofcourse this is unrealistic. But for comparison sake, this is the maximum number of data signals that would be generated, if 5 stations were reporting reliably on an hourly basis for 365 days. The table below shows some results of some data mining that (only for 2018) the total number of data points recorded measured by counting the number of end time stamps (in the column ‘TotalTimeStamps’)
FileName Data Shape AirQualityStationEoICode TotalTimeStamps UniqueTimeStamps FirstTimeStamp LastTimeStamp
Data/BG_5_9572_2018_timeseries.csv (6096, 17) [BG0050A] 6096 6051 2018-01-22 02:00:00 +01:00 2018-09-14 22:00:00 +01:00,
Data/BG_5_9642_2018_timeseries.csv (6050, 17) [BG0040A] 6050 6005 2018-01-23 09:00:00 +01:00 2018-09-14 22:00:00 +01:00,
Data/BG_5_9421_2018_timeseries.csv (5964, 17) [BG0052A] 5964 5919 2018-01-19 21:00:00 +01:00 2018-09-14 21:00:00 +01:00,
Data/BG_5_9616_2018_timeseries.csv (5448, 17) [BG0073A] 5448 5403 2018-01-20 11:00:00 +01:00 2018-09-14 11:00:00 +01:00,
Data/BG_5_60881_2018_timeseries.csv (6004, 17) [BG0079A] 6004 5997 2018-01-03 03:00:00 +01:00 2018-09-14 18:00:00 +01:00]
The total time stamps reported across all five stations in 2018 is 29,562 in the reporting period between 2018-01-03 03:00:00 +01:00 (the earliest reported data signal from any station) to 2018-09-14 18:00:00 +01:00] (the last reported data signal in the data set available). This number seems believable given the average we saw earlier across all 5 stations.
In theory, the next 3 months would produce 10920 data signals. If the system were to report these many data signals, it would bring the total reported data signals in 2018 to **40,482
Of the total possible data signals in a theoratically 100% reliable system of 219,000 the official stations are only generating 40,482.
This is only ##18.5% of possible signal generation (in theory). Is this sufficient or can the official stations do more with the top of the line equipment?
This lends me to conclude that perhaps there is ample opportunity across people, process and technology to deliver a more reliable measure of data signals that is at least 70-80% of theoretical possible data signals. Just this could provide a lot more perspective to the problem. Ofcourse, there maybe other reasons, governmental or otherwise that may prevent the improvement in this area.
A good goal for the Official Stations For Data Signal Reporting Reliability would be 153,300/year at 70% of theoretical max
Feature Engineering and cleanup
With the data we have, I wanted to get to a point where I can run a few quick initial runs with the official data before combining everything. To that end, I engineered a few features for consideration that I thought would make the training better. The following code loads the official data from all files and merges them and adds new columns for new features.
##
# Function: build_master_data_of_pollution_location
# get lat/long data from meta data and merge to eea files for master data.
# input: a list of full path file names that are CSV
# return: list of file name and merged data frame of pollution concentration data and location meta data
#
# left.join(right, on=key_or_keys)
# pd.merge(left, right, left_on=key_or_keys, right_index=True,
# how=’left’, sort=False)
##
def build_master_data_of_pollution_location(aListOfFiles):
master_df = pd.DataFrame()
for aFile in aListOfFiles:
#print(“file: “, aFile)
file_df = pd.DataFrame(load_pollution_measurement_data(aFile))
#print(“file_df.shape: “, file_df.shape)
#create a concatenated dataframe from each of the data frames
#loaded from the file.
master_df = master_df.append(file_df)
#print(“build_master_data_of_pollution_location : master_df.shape: before meta merge “, master_df.shape)
# shape should be: master_df.shape: (39715, 17)
#load the metro_meta_data_file – this has the common station names, elevation, Lat/Long for stations.
meta_data_df = load_metro_meta_data_file(EEA_DATA_METADATA_FILE)
master_df = master_df.merge(meta_data_df, on=’AirQualityStationEoICode’, suffixes=((‘EEA’, ‘META’)))
master_df = master_df.set_index(master_df[‘DatetimeEnd’])
#FEATURE ENGINEERING:
# Add column for whether a day is working day or not (weekend)
# From data 2013/1/1 is a tuesday with ‘1’ as the day of week.
# This means dayofweek 0,1,2,3,4 are Monday to Friday 5 and 6 are Saturday and Sunday
#print(“dayofweek: {} \t day {}”.format(master_df[‘DatetimeEnd’].dt.dayofweek, master_df[‘DatetimeEnd’].dt.day_name()))
#master_df[‘WORKING_DAY’] = master_df[‘DatetimeEnd’].apply(lambda x: 1 if x.dayofweek <= 4 else 0)
#print(“build_master_data_of_pollution_location : master_df.shape: after meta merge”, master_df.shape)
#FEATURE ENGINEERING:
#AirQualityStationType has values ‘background’ or ‘traffic’ convert this to binary flag
master_df[‘STATION_TYPE’] = master_df[‘AirQualityStationType’].apply(lambda t: 1 if(t == ‘background’) else 0)
master_df[‘IS_PM10’] = master_df[‘AirPollutantEEA’].apply(lambda t: 1 if(t == ‘PM10’) else 0)
#0 for hour
#1 for day
#2 for var
master_df[‘LEVEL_OF_DETAIL’] = master_df[‘AveragingTime’].apply(lambda t: 1 if(t == ‘day’) else 2 if (t==’var’) else 0)
#AirQualityStationEoICode
master_df[‘STATION_CODE’] = master_df[‘AirQualityStationEoICode’].apply(lambda c : 0 if (c == ‘BG0040A’)
else 2 if (c == ‘BG0050A’)
else 3 if (c == ‘BG0052A’)
else 4 if (c == ‘BG0054A’)
else 5 if (c == ‘BG0073A’)
else 6 if (c == ‘BG0079A’)
else 9999)
return master_df
#test
fList = build_pollution_data_fullpaths()
master_data = build_master_data_of_pollution_location(fList)
below are few rows from the official data set after feature engineering. I will later select only relevant columns for training.
| CountrycodeEEA | NamespaceEEA | AirQualityNetworkEEA | AirQualityStationEEA | AirQualityStationEoICode | SamplingPointEEA | SamplingProcessEEA | SampleEEA | AirPollutantEEA | AirPollutantCodeEEA | … | AirQualityStationType | Projection | Longitude | Latitude | Altitude | WORKING_DAY | STATION_TYPE | IS_PM10 | LEVEL_OF_DETAIL | STATION_CODE | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| DatetimeEnd | |||||||||||||||||||||
| 2013-01-01 23:00:00 | BG | BG.BG-ExEA.AQ | NET-BG001A | STA-BG0052A | BG0052A | SPO-BG0052A_00005_100 | SPP-BG_A_BETA_andersenFH62IR | SPO_F-BG0052A_00005_100_100 | PM10 | http://dd.eionet.europa.eu/vocabulary/aq/pollu… | … | background | EPSG:4979 | 23.400164 | 42.666508 | 548 | 1 | 1 | 1 | 1 | 3 |
| 2013-01-02 23:00:00 | BG | BG.BG-ExEA.AQ | NET-BG001A | STA-BG0052A | BG0052A | SPO-BG0052A_00005_100 | SPP-BG_A_BETA_andersenFH62IR | SPO_F-BG0052A_00005_100_100 | PM10 | http://dd.eionet.europa.eu/vocabulary/aq/pollu… | … | background | EPSG:4979 | 23.400164 | 42.666508 | 548 | 1 | 1 | 1 | 1 | 3 |
| 2013-01-03 23:00:00 | BG | BG.BG-ExEA.AQ | NET-BG001A | STA-BG0052A | BG0052A | SPO-BG0052A_00005_100 | SPP-BG_A_BETA_andersenFH62IR | SPO_F-BG0052A_00005_100_100 | PM10 | http://dd.eionet.europa.eu/vocabulary/aq/pollu… | … | background | EPSG:4979 | 23.400164 | 42.666508 | 548 | 1 | 1 | 1 | 1 | 3 |
| 2013-01-04 23:00:00 | BG | BG.BG-ExEA.AQ | NET-BG001A | STA-BG0052A | BG0052A | SPO-BG0052A_00005_100 | SPP-BG_A_BETA_andersenFH62IR | SPO_F-BG0052A_00005_100_100 | PM10 | http://dd.eionet.europa.eu/vocabulary/aq/pollu… | … | background | EPSG:4979 | 23.400164 | 42.666508 | 548 | 1 | 1 | 1 | 1 | 3 |
| 2013-01-05 23:00:00 | BG | BG.BG-ExEA.AQ | NET-BG001A | STA-BG0052A | BG0052A | SPO-BG0052A_00005_100 | SPP-BG_A_BETA_andersenFH62IR | SPO_F-BG0052A_00005_100_100 | PM10 | http://dd.eionet.europa.eu/vocabulary/aq/pollu… | … | background | EPSG:4979 | 23.400164 | 42.666508 | 548 | 0 | 1 | 1 | 1 | 3 |
Removed DatetimeBegin, DatetimeEnd, AveragingTime
#’CountrycodeEEA’, ‘AirQualityStationEEA’, ‘AirQualityStationEoICode’,
cols = [‘IS_PM10’, ‘LEVEL_OF_DETAIL’, ‘STATION_CODE’,
‘Concentration’, ‘Verification’, ‘Validity’, ‘Longitude’, ‘Latitude’,’Altitude’,’WORKING_DAY’,
‘STATION_TYPE’]
print(“master_data shape: {}”.format(master_data.shape))
clean_data = master_data[cols]
print(“clean_data shape: {}”.format(clean_data.shape))
Create Train, Dev, Test examples
Just for the official data from the stations, I have 39715 rows and 16 selected colums.
Training: 70% = 27,800 training sampels Test : 20% = 7944 test samples Dev: 10% = 3971 dev samples
training_data = clean_data[0:27800]
test_data = clean_data[27800:35744]
dev_data = clean_data[35744:39715]
print(“training_data.shape: {} \t test_data.shape: {} \t dev_data.shape: {}\r”.format(training_data.shape, test_data.shape, dev_data.shape))
train_X, train_Y = training_data.drop(‘Concentration’, axis=1), training_data[‘Concentration’]
test_X, test_Y = test_data.drop(‘Concentration’, axis=1), test_data[‘Concentration’]
dev_X, dev_Y = dev_data.drop(‘Concentration’, axis=1), dev_data[‘Concentration’]
print(“TRAINING DATA SAMPLE”)
train_Y.head(10)
Two implementations so far showed poor results.
Below is is the prediction from a simple randomforest prediction that didn’t perform well at all on the data set. This maybe an error in my code or just the nature of the data, but this needs more exploration.
| DatetimeEnd | Concentration | PREDICTION |
|---|---|---|
| 2018-03-30 00:00:00 | 50.71 | 49.529923 |
| 2018-03-30 01:00:00 | 52.87 | 49.529923 |
| 2018-03-30 02:00:00 | 40.80 | 49.529923 |
| 2018-03-30 03:00:00 | 35.46 | 49.529923 |
| 2018-03-30 04:00:00 | 36.34 | 49.529923 |
| 2018-03-30 05:00:00 | 29.78 | 49.529923 |
| 2018-03-30 06:00:00 | 26.14 | 49.529923 |
| 2018-03-30 07:00:00 | 35.53 | 49.529923 |
| 2018-03-30 08:00:00 | 47.30 | 49.529923 |
| 2018-03-30 09:00:00 | 28.53 | 49.529923 |
| 2018-03-30 10:00:00 | 24.42 | 49.529923 |
| 2018-03-30 11:00:00 | 22.86 | 49.529923 |
| 2018-03-30 12:00:00 | 19.87 | 49.529923 |
| 2018-03-30 13:00:00 | 16.80 | 49.529923 |
| 2018-03-30 14:00:00 | 16.01 | 49.529923 |
Using the normalized scaled training data set, I used a bidirectional LSTM using Keras over tensor flow. The following result shows the model accuracy and loss. Given this is time series data, my initial idea is to leverage a many to one LSTM as a sequence model for the time series data. 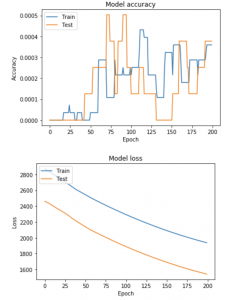
The predictions seem quite a bit out of phase and also accuracy is very low. The Adam optimizer did poorly compared to RMSProp. This is something I need to explore more.
Week3 (inserting notebook)
This week was tough – got very little time to work on the project but also ran into a situation where I had to learn about multiple new python libraries for spatial manipulation. If you have trouble viewing workbook, let me know.
SofiaPollutionPrediction_Week3
9 thoughts on “Data Exploration, Observations, Planning”
Your assignments to peer review (and give feedback below the coresponding articles) for week 1 of the Monthly challenge are the following teams:
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-newbees/
https://www.datasciencesociety.net/air-quality-week-1/
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-banana/
This is very good and thorough. I am convinced that you know what you are doing, and have come up with a plan to proceed. I did notice that you seem to be planning to group observations (average them?) into a single observation/day, rather than the current hourly information. It seems to me like this would be losing a significant amount of information, particularly if the ultimate goal is to create predictions for an entire 24 hr interval. I think perhaps you should try to use a Jupyter notebook in the future for cleaner presentation of your code.
Hello, This is very good initial report. This describe the thought process clearly and written down the report accordingly.
Hi! This is very good and detailed description from the first week, I look forward to seeing your update in a Week 2!
Your assignments to peer review (and give feedback below the coresponding articles) for week 2 of the Monthly challenge are the following teams:
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-jacob-avila/
https://www.datasciencesociety.net/air-sofia-pollution-case/
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-kiwi-team/
Great article!
Your approach to the case is really impressive and shows a good past practice. As beginners, we are pleased to have the opportunity to get to know your method for each step in the race. The Tableu visualizations are very informative and we have received useful information about aspects that we have not inspected so far.
We are looking forward for your Week 3 resolution. Good luck!
Team Kiwi (:
Your assignments to peer review (and give feedback below the coresponding articles) for week 3 of the Monthly challenge are the following teams:
https://www.datasciencesociety.net/sofia-air-quality-eda-exploratory-data-analysis/
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-kung-fu-panda/
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-iseveryonehigh/
Hello Kams, thanks for sharing these extensive progresses of your! Your initial analysis is amazingly well detailed. I’ll mainly focus on your latest update : have you tried simple methods as a benchmark? What common metric would you use to assess on prediction’s performance? I am deeply intrigued by your use of such sophisticated methods, RF and LSTM, the later being particularly interesting for time series modeling. Surprising to have such constant predictions from RF (might be an hyper parameters issue). Are you sure the NN’s loss converged properly ? Your loss shape looks like an under fitting. Best
Your assignments to peer review (and give feedback below the coresponding articles) for week 4 of the Monthly challenge are the following teams:
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-lone-fighter/
https://www.datasciencesociety.net/sofia-air-week-1/
https://www.datasciencesociety.net/monthly-challenge-sofia-air-solution-jeremy-desir-weber/