
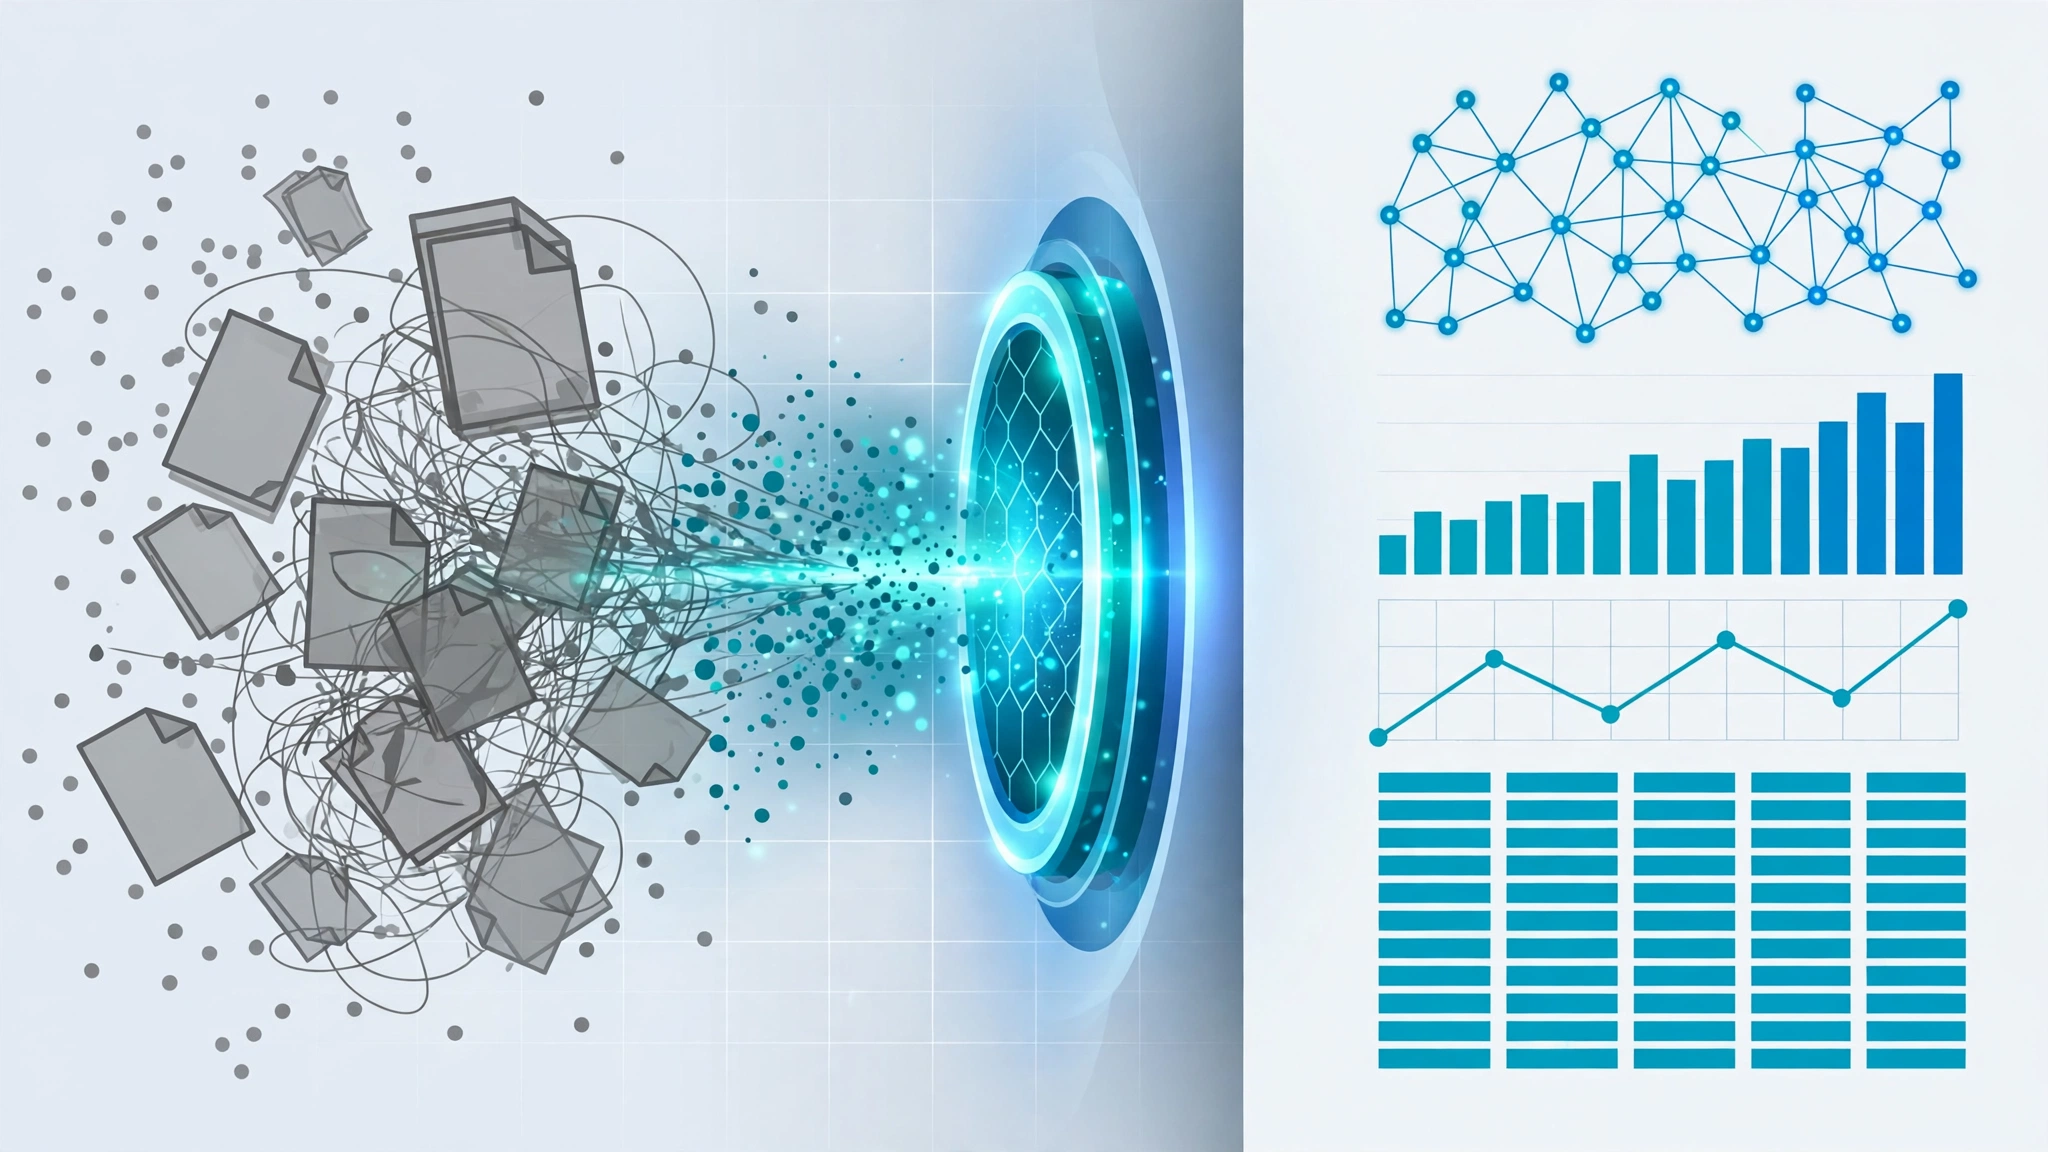
Ask a room full of data scientists what made their last AI project succeed, and very few will name the model.
They will talk about the data. The months spent cleaning it. The labels that were wrong. The duplicate records nobody noticed until the results stopped making sense. It is not the glamorous part of AI, so it rarely gets the headline. But it is usually the part that decides whether a project works or quietly falls apart.
That gap between what gets attention and what actually matters is worth talking about, especially now. Models are easier to access than ever. A small team can use the same class of AI that a large company uses. The model is no longer the rare advantage. The data behind it is.
The Model Is Only as Honest as Its Data
An AI system learns patterns from the examples it is given. If those examples are messy, incomplete, or biased, the system learns the mess along with the pattern. No amount of computing power fixes that. It just produces wrong answers faster and with more confidence.
This shows up in ordinary ways.
A sales model trained on two years of customer records might look accurate in testing. Then someone notices that half the records from one region were entered twice, and a whole product line is missing because it was stored in a separate sheet. The model was not broken. It was doing exactly what the data told it to do.
Healthcare teams run into a sharper version of the same problem. If historical records reflect who got access to care, and not just who needed it, a model trained on those records can repeat that imbalance while looking perfectly scientific. The numbers are real. The conclusion is still unfair.
That is why experienced practitioners have a plain saying for this: garbage in, garbage out. It sounds old. It keeps proving true.
What “Bad Data” Actually Looks Like
Bad data is rarely dramatic. It is usually a pile of small, boring problems.
Duplicates are the classic one. The same customer, patient, or product appears two or three times under slightly different spellings, and the system treats them as different cases.
Then there are gaps. A field left blank in 30 percent of records does not stay neutral. The model works around it, leans on other signals, and sometimes lands on a pattern that has nothing to do with reality.
Outdated data is sneakier. Customer habits change. Prices change. Language changes. A model trained on five-year-old behaviour can be technically correct and practically useless at the same time.
Labels cause some of the worst damage, because everything else builds on them. If two people label the same kind of image or ticket differently, the model gets contradictory lessons. It averages them out into something mediocre, and the team blames the algorithm.
None of these problems announce themselves. The training completes. The dashboard fills with numbers. The flaw only surfaces later, when real users meet the output and it does not hold up.
Why Bigger Models Do Not Save You
There is a tempting belief in AI right now: if results are weak, use a larger model.
Sometimes that helps. Larger models are better at language, reasoning, and handling messy instructions. But scale has a limit, and the limit is the data. A bigger model trained on poor data does not rise above it. It memorizes it more thoroughly. In some cases it gets worse, because a powerful model can fit noise so well that the noise starts to look like a pattern.
Think of it like hiring a brilliant analyst and handing them a spreadsheet full of errors. Their brilliance does not fix the spreadsheet. They will just produce a very polished report built on bad numbers, and polished reports are harder to question.
The smarter spend, for most teams, is earlier in the pipeline. Time on data collection, cleaning, and validation looks slow on a project plan. It is the time that everything else stands on.
The Work That Actually Improves AI Results
Good data work is not mysterious. It is mostly discipline.
Start by knowing where the data came from. Who collected it, when, and for what purpose? Data gathered for billing behaves differently from data gathered for care, even when the fields look the same. Provenance sounds like paperwork until the day it explains a result nobody could understand.
Clean in the open, not in private. When one person quietly fixes a dataset on their own laptop, the fixes vanish with them. Documented cleaning steps, shared with the team, turn a one-off rescue into a repeatable process.
Check the labels like they matter, because they do. Sample them. Have a second person review a slice of the labelled data and measure how often the two agree. Disagreement is not a failure. It is information about where the task itself is unclear.
Keep a holdout set you trust. A small, carefully checked set of examples, kept separate from training, tells you more about real performance than a giant test set built from the same flawed source.
And keep watching after launch. Data drifts. What users type, buy, and click this year is not identical to last year. Teams that schedule regular data reviews catch the drift early. Teams that do not usually meet it as a surprise complaint.
This is also where the newer wave of AI tools raises the stakes. Autonomous systems and assistants that act on data, not just describe it, spread a data error much further than a static report did. If you want a plain-English grounding in how these systems operate, this explainer on how AI agents work is a useful starting point before going deeper.
A Simple Test Before Any AI Project
Before arguing about models, a team can ask five honest questions about its data:
- Can we explain where this data came from, in one sentence each for its main sources?
- Do we know roughly how much of it is duplicated, missing, or outdated?
- If two people labelled the same sample, would they mostly agree?
- Is our test set genuinely separate from our training data?
- Who checks the data again after the system goes live?
If the answers are shaky, the project does not need a bigger model yet. It needs a few weeks of unglamorous work. That is not a delay. That is the project.
The Quiet Advantage
Here is the part that rarely gets said in vendor pitches: good data is hard to copy.
A competitor can access the same models you use. They can hire similar engineers. What they cannot download is ten years of clean, well-labelled, well-understood data about your customers, your operations, or your field. That is why two companies using nearly identical AI technology get very different results. The technology is shared. The data is not.
So the next time an AI project disappoints, resist the first instinct. Do not start by shopping for a bigger model. Open the dataset. Look at the duplicates, the gaps, the labels, the dates. The answer is usually sitting there, in plain sight, in the part of the work nobody puts on a slide.
Better AI rarely starts with a better model. It starts with better data, and with a team willing to do the slow work first.