
Nobody sits around patiently watching a loading spinner anymore. We leave. Close the tab, open a competitor, move on. It sounds dramatic, but it is the truth, and every product team building anything consumer-facing knows it.
Here is what is interesting, though. The businesses that figured out speed years ago did not just get lucky with faster hardware. They made completely different architectural decisions. The technology used to implement these systems is much more layered and intricately thought-out than many people are aware.
The article will detail how each layer of the stack created a working product, and will also examine how different industries have taken advantage of some of these principles in completely different ways.
First, What Actually Qualifies as Real-Time?
The phrase gets stretched so thin in marketing that it is worth pinning down. In engineering, a real-time system has a hard or soft time constraint on its response. Miss that window, and you have failed, even if the output is technically correct.
Hard real-time means no exceptions, ever. Examples of soft real-time systems that may affect people’s lives include the software that controls the flight of airplanes and the monitoring equipment in hospitals. These types of systems typically have a high priority for meeting deadlines, so any delay in their response could lead to loss of life. However, with soft real-time systems, users will experience some delays on occasion while also experiencing some pattern of delays that degrades their experience in ways they are aware of.
The majority of what consumers interact with in today’s marketplace is contained within this soft real-time environment. But the bar keeps moving. A decade ago, a two-second page load was considered fine. Now, research shows that a 200-millisecond delay in checkout can measurably hurt conversion. The threshold of user tolerance is basically shrinking every year.
So when we talk about real-time systems in the context of consumer products, we are talking about systems engineered to respond in under a few hundred milliseconds, consistently, at scale, regardless of load spikes.
The Stack Is Not One Thing. It Is Several Layers Working in Concert.
This is the part that trips people up. There is no single tool, database, or framework you can adopt to suddenly have real-time systems. What you need is a set of layers that each solve a different piece of the latency problem, and then tight integration between them so they do not introduce friction at the seams.
Layer One: Get Computation Physically Closer to the User
No piece of software runs faster than the speed of light will allow. If your servers are in Frankfurt and your user is in Chennai, that round-trip physics tax is real and unavoidable. Edge computing is the answer to this.
Instead of every request routing back to one central origin server, computation and content get distributed to points of presence that are geographically close to whoever is making the request. CDNs have been doing this for static assets for years. What changed recently is that edge infrastructure can now run actual logic, not just cache files.
- Cloudflare Workers and Vercel Edge Functions allow code to execute at the CDN layer, before the request ever hits your origin.
- GeoDNS intelligently routes users to the nearest healthy cluster, automatically, without any application code doing the work.
- Regional data replication keeps frequently needed data physically close, so reads do not require a cross-ocean trip.
In travel and hospitality, this is what makes the difference between a booking confirmation that appears in half a second versus one that takes four. A traveler in Singapore booking a hotel in Rome should not have to wait for a round-trip to a server that happens to be in Ohio.
Layer Two: Stop Asking. Start Listening.
Traditional architectures poll. Service A asks Service B for data on a schedule. Did anything change? No? Okay, ask again in five seconds. This model is simultaneously wasteful and slow. You burn cycles doing nothing, and then you still have a five-second gap between when something happens and when you know about it.
Event-driven architecture flips this. Services do not ask for data. They subscribe to event streams and react the moment something relevant occurs.
- Apache Kafka is the dominant infrastructure here. It handles millions of events per second with durability and replay capabilities baked in.
- RabbitMQ and AWS SNS/SQS handle lighter workloads where Kafka might be overkill.
- WebSockets and Server-Sent Events push updates from backend to frontend the instant state changes, so users see live data without refreshing anything.
For BFSI and fintech companies, this is not a nice-to-have. When a transaction looks like fraud, the window to act is measured in milliseconds, not seconds. Real-time systems built on event-driven architecture catch that pattern and trigger a block before the payment settles. A batch job running every thirty minutes would never catch it in time.
The same principle applies to livestock prices, balance updates, and transfer confirmations. Users expect these things to reflect reality now, not five minutes ago.
Layer Three: Keep the Hot Data in Memory
Hitting a database on every single read is one of the most reliable ways to watch your performance fall apart under load. Disk reads are slow. Network calls to a database add latency. And traditional relational databases start showing their limits when thousands of concurrent queries land simultaneously.
Caching is the solution, and it is not glamorous, but it is probably responsible for more performance wins per hour of engineering effort than almost any other optimization.
- Redis is the tool most teams reach for. It does key-value caching, session storage, pub/sub messaging, rate limiting, and real-time leaderboards all in one.
- Memcached works well for straightforward, pure key-value caching where you want something simple and extremely fast.
- Distributed caching layers like Apache Ignite and Hazelcast let you scale caching horizontally across clusters without hitting a single node ceiling.
In e-commerce, caching is what keeps a product page loading instantly, even when 80,000 people are browsing the same item during a sale event. The inventory count, pricing, and product description are all served from memory. The database sees a fraction of the traffic it would otherwise.
And yes, that ‘only 3 left!’ message needs to reflect real inventory. Which means your cache invalidation strategy matters just as much as the cache itself.
Layer Four: Microservices and the Art of Scaling Only What Needs Scaling
Monolithic applications are not inherently bad, but they have one fatal flaw for real-time systems under variable load. When one part is stressed, everything slows down. You can’t just scale the checkout service while the rest of the application is working correctly.
Microservices allow for an application to be broken up into parts (services) that can be individually deployed. Each service has a different responsibility. For instance, the checkout service can now scale independently of the product catalog service and the recommendation engine.
- Each microservice has been packaged in a Docker container along with its associated libraries and other dependencies, enabling more predictable and faster deployment of each service to an environment.
- Kubernetes has been developed to manage larger numbers of Docker containers at scale by using container orchestration techniques to add or remove containers automatically based on the demand for services.
- A service mesh (e.g., Istio) provides a way for services to communicate with one another and perform many other functions – such as load balancing, retrying requests, circuit breaking, performing mutual authentication, and performing distributed tracing.
A fintech platform processing loan applications benefits enormously from this model. The document verification service might need twelve instances during peak hours. The notification service might need two. With microservices and Kubernetes, each scales to exactly what it needs, independently, without over-provisioning the whole system.
Layer Five: AI and Voice at the Speed of Conversation
This layer did not really exist five years ago in the way it does now. Real-time systems are increasingly being asked to not just serve pages fast but to hold conversations intelligently and instantly.
The challenge of AI architecture is that the process of inference is computationally heavy. The key is to structure your systems such that the response from the AI feels immediate while the model is actually working hard behind the scenes.
- Streaming inference serves model outputs token by token as they generate, rather than waiting for the full response, so users see text appearing rather than a blank screen followed by a wall of text.
- Quantization and distillation models are used to compress AI models to operate in a more cost-efficient manner; this allows for responses to be achieved in less than 100ms on affordable hardware.
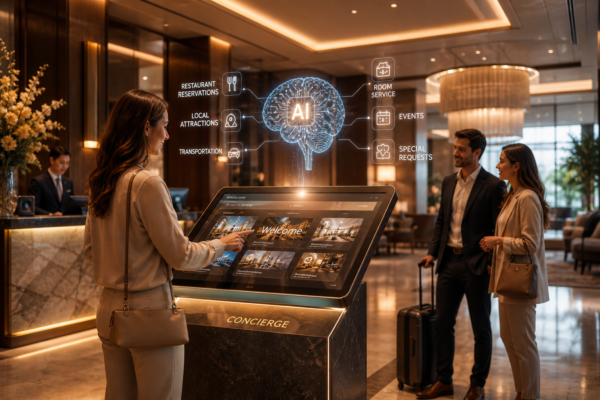
- A voice AI platform combines the following: speech recognition, intent recognition, and text-to-speech; this creates an end-to-end pipeline that is capable of providing real-time voice interaction. This functionality is currently used within banking support centers, airline reservation services, and hotel concierge services.
Voice-based real-time systems (particularly in the travel and hospitality industry) have dramatically changed the way guests interact with businesses (properties in particular) – i.e., a guest requesting to change their checkout date or requesting additional towels will receive a response within one second without the need to listen to ‘hold’ music or wait for a front desk agent.
Layer Six: Databases Built for Now, Not Just Consistency
Traditional relational databases are exceptional at what they do. ACID compliance, complex joins, transactional integrity, all critical capabilities. However, these databases were not designed to support thousands of users writing at once while providing them with responses in less than 10 ms.
To meet this need, a new category of databases has been developed to address specific pieces of the real-time challenge.
- Firebase Realtime Database and Firestore enable instant state updates between all clients when the state is changed, making them well-suited to real-time collaborative applications and real-time dashboards.
- Apache Cassandra has an incredibly high write capacity, allowing it to be used by fintech firms to log transactions because each payment can be written without slowing anything down.
- ClickHouse and Apache Druid are columnar analytical engines that allow for real-time analytics on dashboards. Instead of retrieving data from a nightly batch, teams will now see metrics update in real-time as events come in.
- CockroachDB and YugabyteDB offer distributed SQL, PostgreSQL-compatible syntax with the horizontal scalability that global BFSI operations need to serve customers across dozens of regions without data silos.
For e-commerce, real-time inventory databases mean the difference between showing a customer accurate stock information and accidentally selling 400 units of something you only had 12 of.
Knowing When Things Go Wrong Before Users Tell You
There is a category of engineering that rarely gets celebrated but matters enormously: observability. The best real-time systems in the world are not the ones that never have issues. They quickly show teams what problem(s) are being encountered and allow them to quickly troubleshoot the cause of the problem(s), rather than taking days to troubleshoot the problem(s).
- Using distributed tracing utilizing OpenTelemetry and Jaeger provides a comprehensive view of a single request through all microservices that were involved in processing the request, as well as identifying which hop introduced latency to the overall latency of the request.
- Using Prometheus and Grafana, teams have access to real-time dashboards that display their system(s) health and alert them before the point in time that any of their end users will experience degradation of service.
- Using circuit breakers (Resilience4j), teams can isolate failing services automatically so that no other service(s) dependent on the failed service(s) will experience degradation of service as a result of a single slow component.
- Using chaos engineering (conducting intentional failure experiments with services running in staging) will allow teams to create confidence that their service(s) will continue to function normally if a system failure occurs in production.
In BFSI, the regulatory dimension makes this even more critical. A payment gateway experiencing degraded performance during peak trading hours is not just a user experience problem. It is a compliance problem. Teams need sub-second alerting and automated remediation, not a support ticket opened by a frustrated customer.
Conclusion
Speed in software is not accidental. Every digital experience that seems easy to use has been carefully created because of one or more decisions made long before a person ever touches a product – usually a couple of years prior, when the architecture of the product was established. Companies have successfully optimized their performance over a long period of time by preparing their products for performance optimization, rather than just discovering it.
The technology stack explored here is not reserved for tech giants with billion-dollar infrastructure budgets. Managed cloud services have democratized access to Kafka, Redis, Kubernetes, and distributed databases to the point where a well-funded startup can deploy the same foundational layers as a global bank. What still separates the fast from the slow is not access to the tools. It is the discipline to use them together, thoughtfully.
If you’re developing a payment system, which must identify fraud in 50 milliseconds; building a travel booking website, which must send booking confirmations to customers in 12 time zones; or developing an e-commerce experience that will run without crashing when 100,000 people are looking at the same page at the same time due to a flash sale, architecture built around real-time systems will be your best solution.